Efficient Urdu Caption Generation using Attention-based LSTMs
Overview
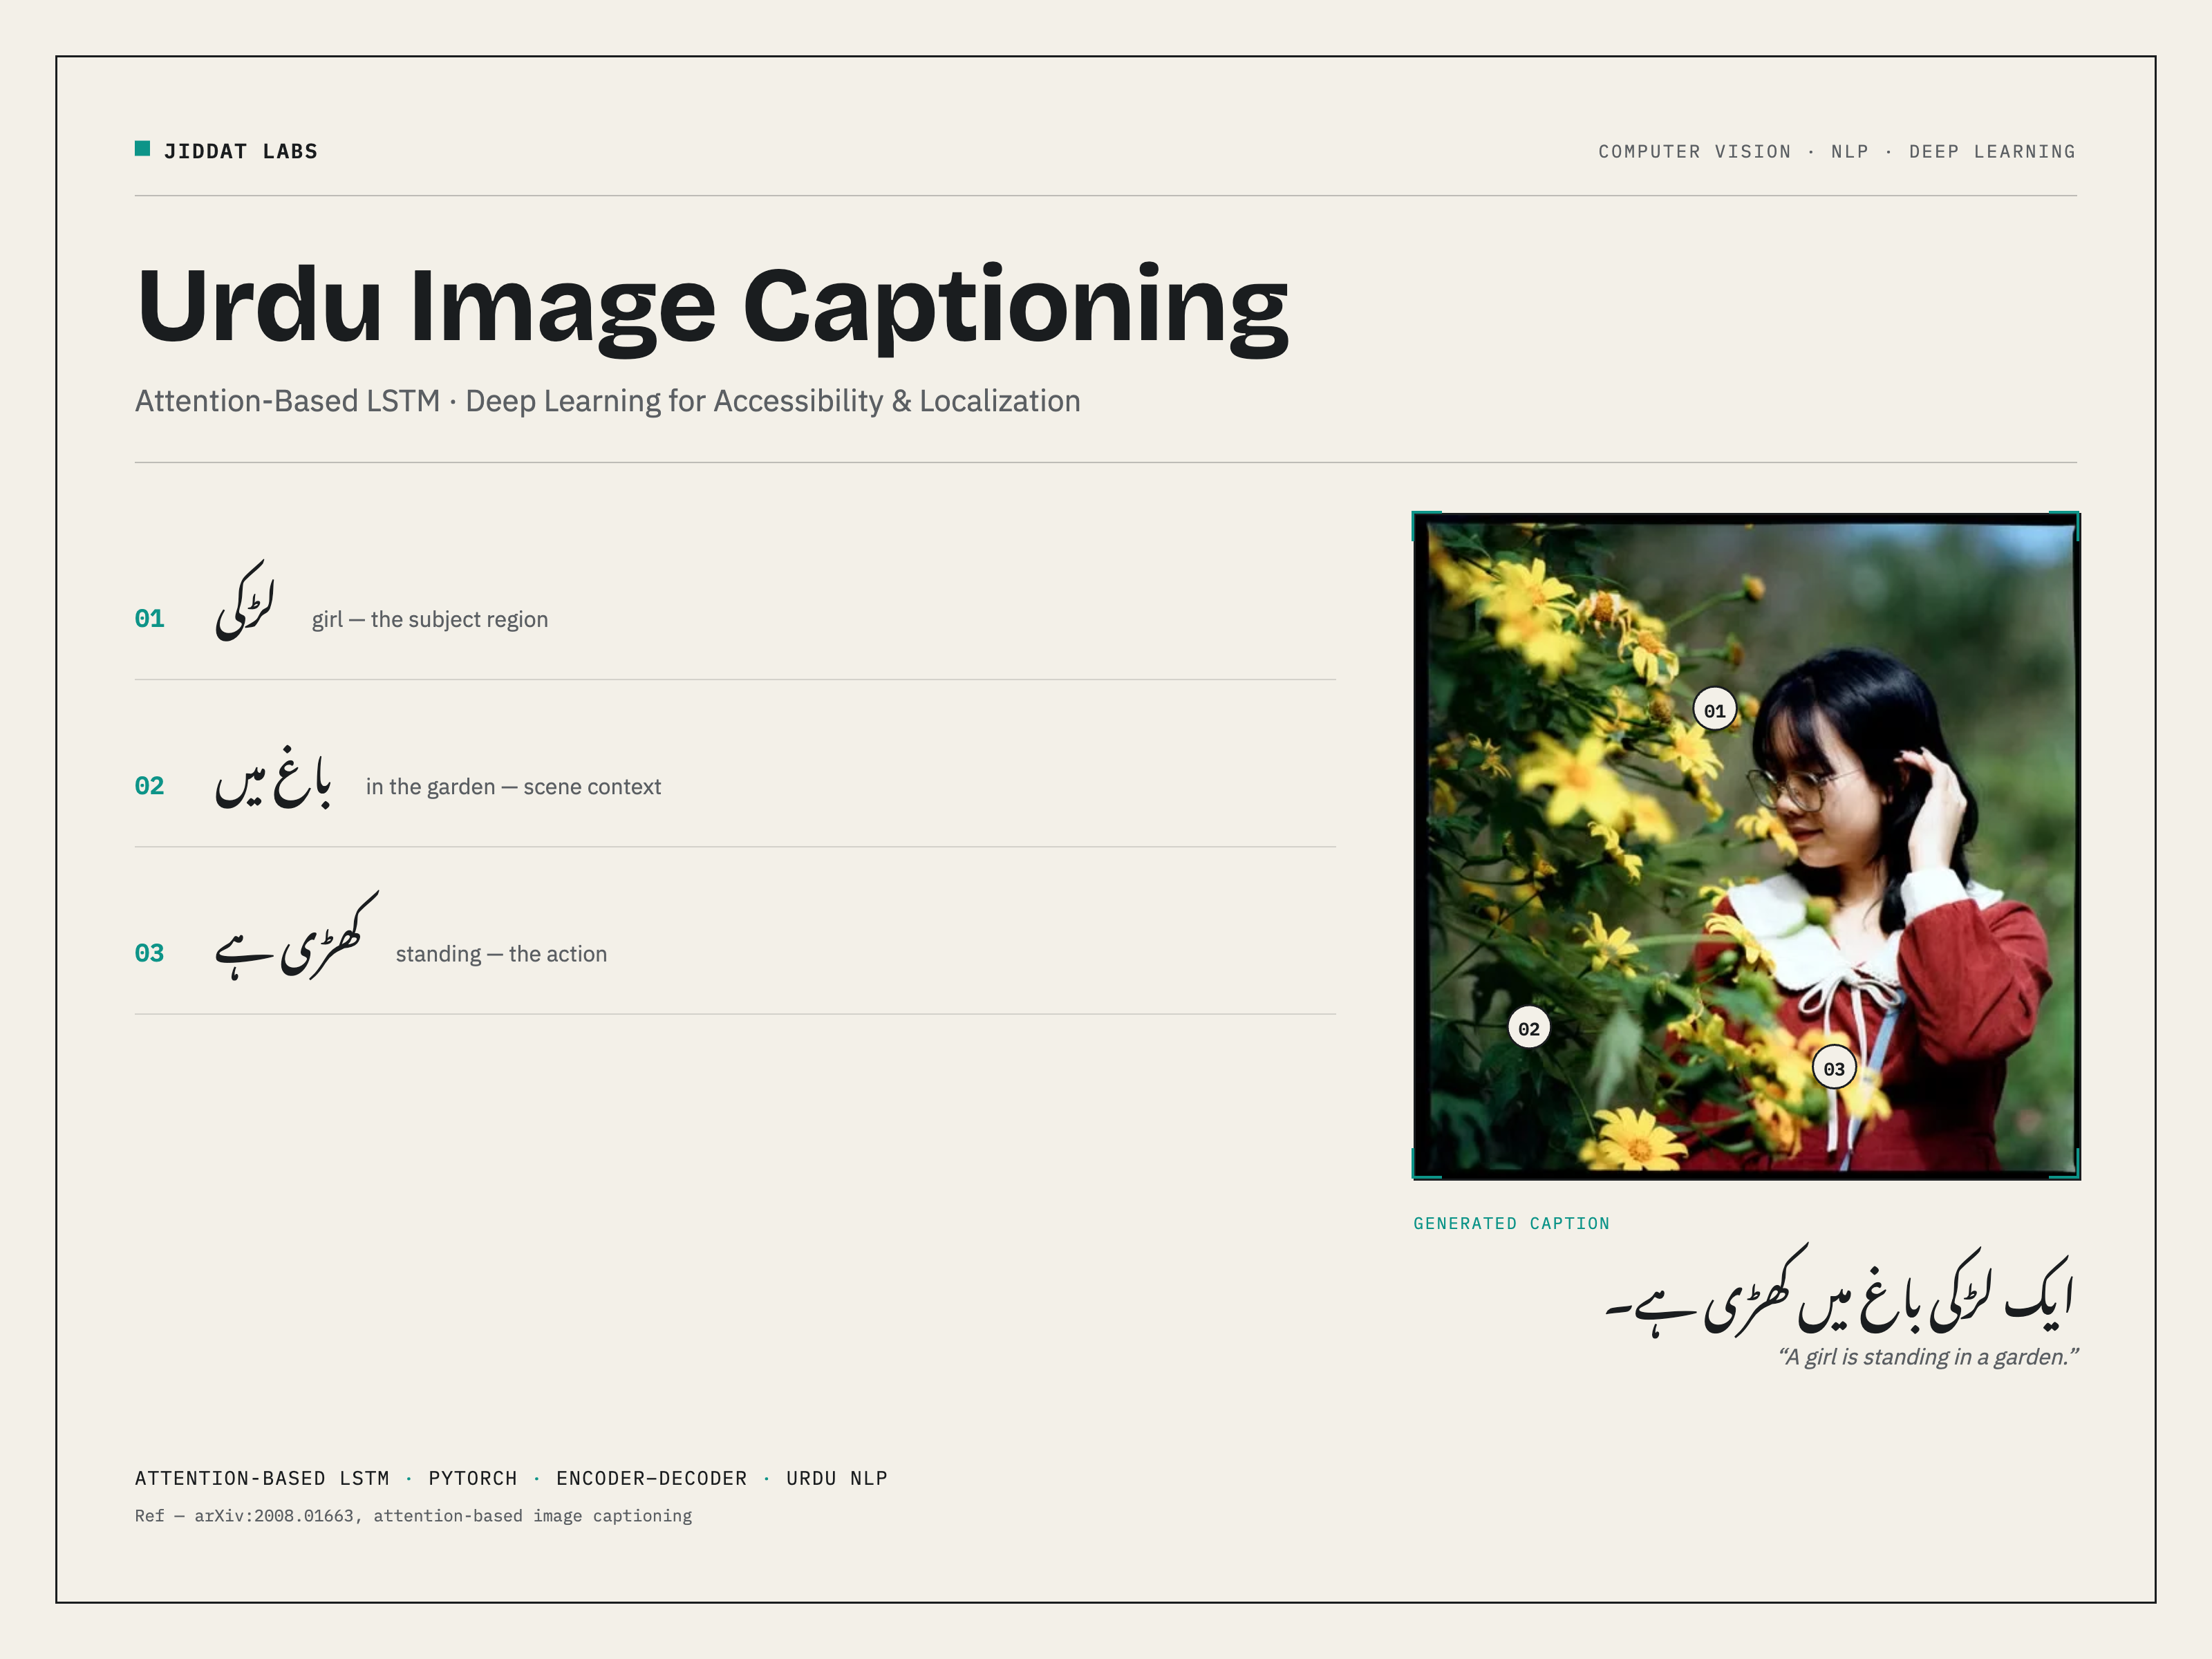
An attention-based LSTM model that generates Urdu-language captions for input images. Image captioning research is built almost entirely on English datasets, so the work began with dataset preparation: assembling images paired with native Urdu captions, because nothing suitable existed to train on. Only once that dataset was in place could the model itself be built — a CNN encoder feeding an attention LSTM decoder — then trained and deployed as an online service that needs no setup to use.
Outcome
One of the first Urdu captioning models of its kind, together with the Urdu image-caption dataset built to train it, and ready to use online with no setup.
Screens & Demos
Architecture & Pipeline
-
01
Dataset Preparation
Images + native Urdu captions
-
02
Image Input
From the prepared dataset
-
03
CNN Encoder
Visual features
- CNN
-
04
Attention LSTM Decoder
TensorFlow
- LSTM
- TensorFlow
-
05
Urdu Caption
Online inference
End-to-end flow, in order. Scroll sideways on a narrow screen.
Key Features
- Dataset preparation from scratch: images paired with native Urdu captions
- Undertaken because no suitable Urdu image-caption dataset existed to train on
- CNN encoder producing visual features for the decoder
- Attention-based LSTM decoder generating the caption
- Trained and deployed for online inference