Large-Scale Web Scraping Pipeline + Dashboard (50M+ Records)
Overview
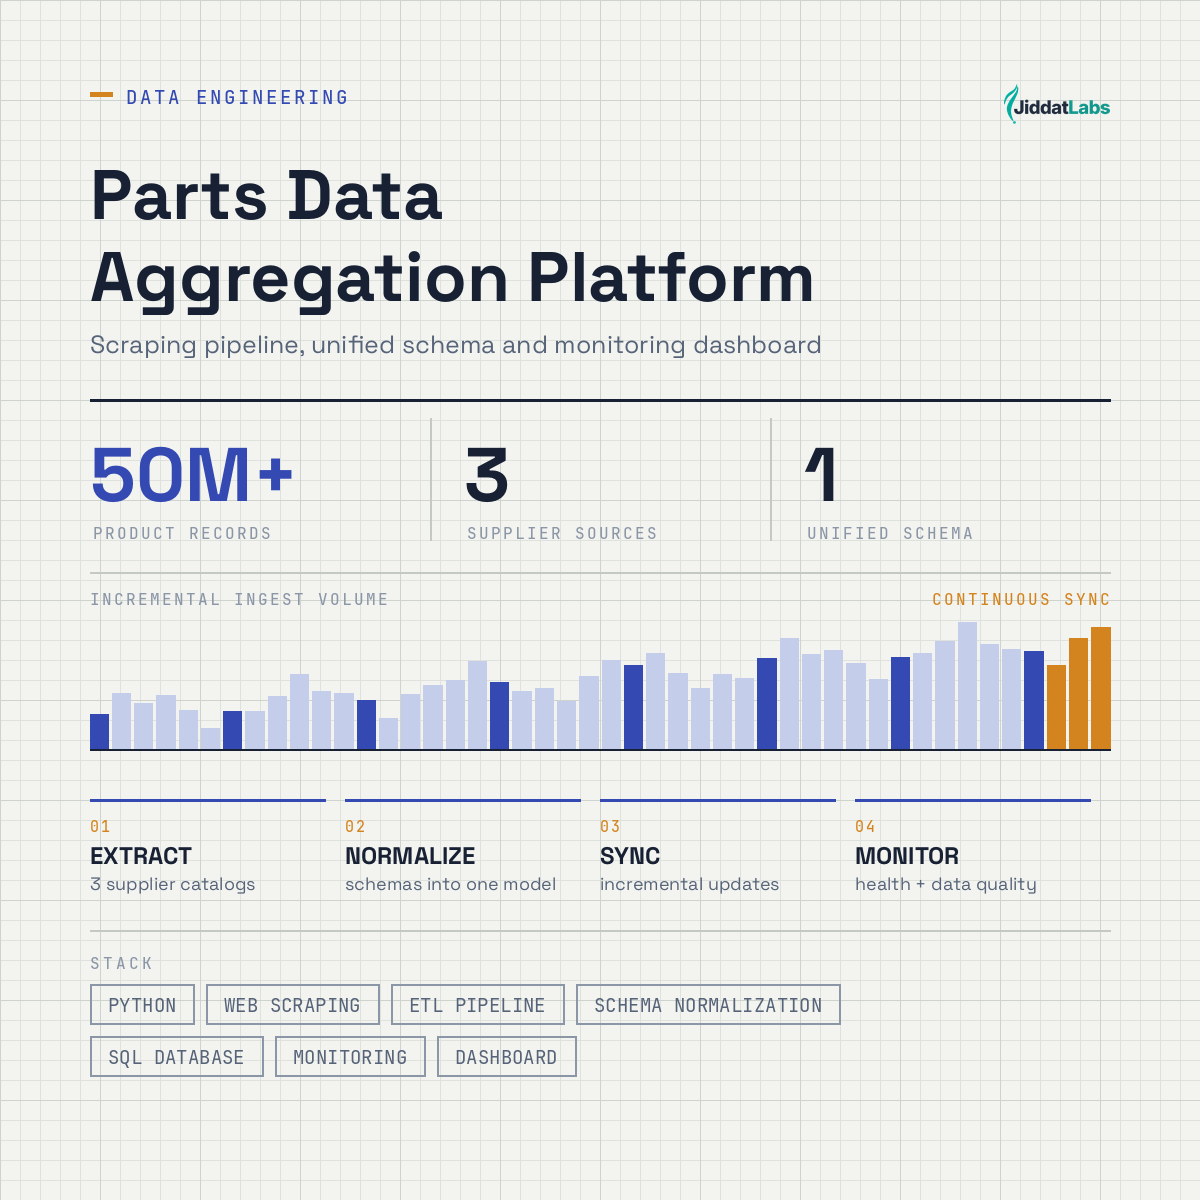
Designed and built the backend and dashboard for a parts-catalog aggregator that ingests over 50 million product records from three high-volume supplier sites. The scraping pipeline handles each site's protections against bots — collection runs through NordVPN sessions rotated across different locations, so requests arrive from varied origins rather than one hammering address — and reconciles their schema differences, with incremental updates feeding a unified PostgreSQL catalog and a FastAPI monitoring dashboard for extraction health and data quality.
Outcome
Replaced fragmented manual extraction with a single 50M+ record catalog the client can query, monitor, and refresh, with full visibility into health for each source and data quality for each field.
Screens & Demos
Architecture & Pipeline
-
01
Supplier Sites (×3)
High-volume parts catalogs
-
02
Per-Site Scrapers
Python · Selenium · Scrapy
- Python
- Scrapy
- Selenium
-
03
Anti-Bot Handling
NordVPN sessions · rotated locations
- NordVPN
-
04
Schema Normalization
Unify per-supplier data models
-
05
Incremental Updates
Diff against last crawl
-
06
PostgreSQL Catalog
50M+ unified records
- PostgreSQL
-
07
FastAPI + Dashboard
Health & data-quality monitoring
- FastAPI
End-to-end flow, in order. Scroll sideways on a narrow screen.
Key Features
- Scraping pipeline covering three sources, each with its own handling for bot detection
- NordVPN sessions rotated across locations, spreading collection across varied origins
- Incremental updates instead of full recrawls (lower cost & latency)
- Unified PostgreSQL schema reconciling differing supplier data models
- Monitoring dashboard for extraction health and data quality
- FastAPI backend exposing the catalog to downstream apps
- Designed to scale to additional supplier sources